The audited one-rune groups show no clear enrichment at the seven mapped structural features in this bounded comparison. The primary, section-conditioned placement test gives a maximum-corrected p of 0.3027. Restricting the comparison to short words or excluding red text does not produce a stronger lead.
Of the 81 singleton tokens outside red spans, 61 have none of the listed features and still represent 26 distinct rune symbols. There is no positive support here for reinterpreting the entire diverse inventory as headings, boundary markers or instructions. This does not prove that every group is an ordinary English word. No new plaintext is recovered.
The premise being checked
Several earlier cipher screens assumed that a one-rune lexical group should decode to an English A or I, sometimes allowing O. Session 43 confirmed the source glyphs and separators, but deliberately left their semantic roles open. Those are different questions.
This session asks whether the locations themselves support a general structural-marker explanation. It does not add a cipher table, choose a literary key, delete inconvenient symbols, or decide what any unknown rune says.
The protocol was saved before calculating these outcomes. Earlier singleton and layout audits were already known, so this is not an independent preregistration.
Inputs and literal features
The scope remains LP2 pages 0–55: 12,956 runes, 2,896 lexical words and 83 singleton tokens spanning 28 symbols. Apostrophes immediately flanked by runes stay joined. A word spanning a printed line or page seam stays one word. The master transcription and all earlier evidence remain unchanged.
Each word receives seven binary labels. An edge counts only when the word starts or ends there; a wrap inside a word does not count.
| Feature | Definition | Singletons observed | Expected under primary comparison |
|---|---|---|---|
| Red span | Overlaps one of the 13 manually aligned red introductory spans retained in Session 57 | 2 | 0.91 |
| Section edge | First or last lexical word of a master-defined section | 0 | 0.47 |
| Paragraph edge | First or last lexical word of a master-defined paragraph | 1 | 0.80 |
| Page edge | Immediately flanks a page seam or the document endpoint | 2 | 1.34 |
| Line edge | Immediately flanks a line/page seam or the document endpoint | 12 | 10.23 |
| Literal stop adjacent | An immediately flanking rune gap contains ., , or ; |
14 | 9.66 |
| Nonrunic data adjacent | An immediately flanking rune gap contains an ASCII letter or digit | 1 | 0.39 |
Counts overlap. Literal punctuation is a transcription label, not an assertion about sentence meaning or a cipher operation. The two red singletons remain M at page 6, rune offset 75, and A at page 54, offset 0. Red opening words on pages 8 and 40 are retained as spans without assuming that they form separate titles.
The physical boundary map is not complete coverage of the book. We therefore do not silently convert every master punctuation label into an image-confirmed semantic stop. Most line, page and punctuation features use the retained transcription; red spans and singleton identities use the earlier source audits. The results pin the derived boundary map for provenance but do not apply its partial shape corrections as universal semantics.
Matched placement comparison
Within each section, randomly assign the same number of singleton labels to the eligible word positions. The rune stream and boundaries do not move. The nine-rune number-label section has no singleton and contributes no variation.
For each feature, calculate its expected count and variance from stratified hypergeometric sampling. The primary statistic is the largest positive standardized excess across the nonconstant features. Each of 9,999 reference draws uses that same maximum, so we do not select the most favorable feature afterward and report it alone.
The largest observed excess is literal punctuation adjacency: 14 against 9.66 expected, standardized excess 1.51. In 3,026 reference draws the maximum is at least as large, giving the plus-one comparison 0.3027.
| Comparison | Eligible words | Singleton labels | Maximum-corrected p |
|---|---|---|---|
| Primary: all words, conditioned on section | 2,896 | 83 | 0.3027 |
| Secondary: one- through three-rune words | 1,251 | 83 | 0.3847 |
| Secondary: exclude all red-span words | 2,865 | 81 | 0.3914 |
| Secondary: short words outside red spans | 1,237 | 81 | 0.2897 |
The secondary comparisons are sensitivity checks, not independent discoveries. Excluding red spans removes 31 words from the candidate pool, including two singletons. It changes no rune, separator or original boundary label. The remaining singleton inventory still spans 28 symbols.
The short-word comparison partly addresses typesetting and word-length differences, but is not an exact length match. These are conditional placement references, not a model of English grammar. An unremarkable result cannot establish that the words are English; an enrichment would not by itself establish that they are instructions.
Controls and ordinary solved words
An artificial placement control puts all 83 selected labels at eligible word-aligned line edges while preserving each section's count. The same statistic detects it at p = 0.0001, the minimum available with this reference size. That verifies sensitivity to a strong location signal, not power against every subtle marker pattern.
The five already decoded LP1 reference groups contain 483 lexical words and 14 singletons, all A or I. Four of those ordinary words sit at line/page/document edges; three are adjacent to literal punctuation. In the koan, A follows its heading stop and two I tokens follow punctuation before quoted speech. A structural location therefore cannot, by itself, distinguish an ordinary word from a control symbol. Red spans were not evaluated in these solved controls, and this small sample is not used as a universal grammatical benchmark.
Mapping fixtures verify that within-word line and page wraps are not classified as word edges, apostrophe groups remain joined, and adjacent nonrunic data remains visible in the gaps. Every real singleton links back to its earlier source-inspection record, including the red initial's distinct audit status. Direct feature sums agree with the reported observed counts.
What remains after excluding the obvious exceptions
Among the 81 singletons outside red text, 61 lack every listed feature. These 61 cover 26 symbols. For example, the EA at page 0, offset 176 remains surrounded by ordinary word separators in its retained source crop, with no listed structural feature.
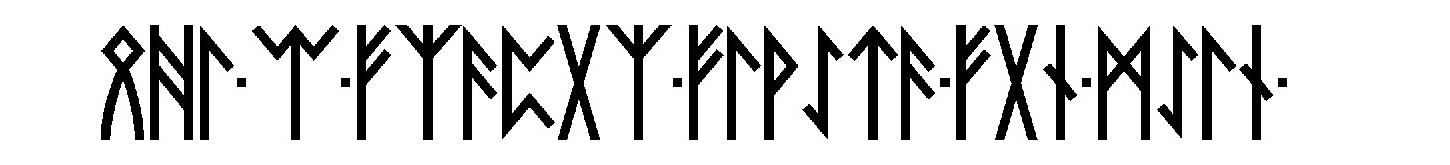
This observation makes the two red tokens an insufficient explanation for the inventory's diversity. It also gives no basis for declaring the other 61 tokens meaningless markers. A local abbreviation, numeral, unusual vocabulary item or untested structural role remains possible; none is identified by this experiment.
This test covers seven features, not every possible pattern in the book. It does not search glyph sequences, illustrations, negative-space shapes or hypothetical ritual meanings. Introducing such a role would require an independently motivated prediction and source checks rather than a label chosen to rescue a failed cipher.
Reproduce and inspect
Run beside the retained evidence files with Python and NumPy:
python3 -B singleton_role_audit.py
- Fixed protocol and limits
- Placement implementation and controls
- Complete comparisons, all word positions, singleton audit links and solved controls
- Thirteen red-span source alignments
- Partial physical boundary ledger
- Singleton source observations
- Earlier observations including apostrophe corrections and the red initial
- Lexical grouping helper, reference groups, rune loader
- Unchanged master transcription
Master SHA-256: b0b2e13c3cd35512ee5955a2d9a56c22d7410e283d35dd9c90abbaa7b99279eb. The script checks it, records input and implementation hashes, and leaves earlier results intact.
Decision
Park the general structural-marker explanation at this scope. Preserve the conditional A/I constraint, with its language and boundary assumptions attached; do not convert it into a proven plaintext identification.
A useful next bounded task is an image-first full rune-and-separator reading of LP2 pages 0–2, the complete 729-rune opening section. The previous fresh-reading check covered six other pages, not this complete section. Freeze the reading and uncertainties before comparison, then check the repetition and word constraints on the reconciled source. The reading would not be fully blind because these pages have already appeared in prior research. This is a source-quality task, not a promised decipherment.
No verified new plaintext is found. The result removes one proposed escape from the singleton constraint without asserting that all other interpretations are impossible.